DeepSeek Just Released V4.1-Flash-1017, Scores 77.0 on DeepSWE, Opens Search API
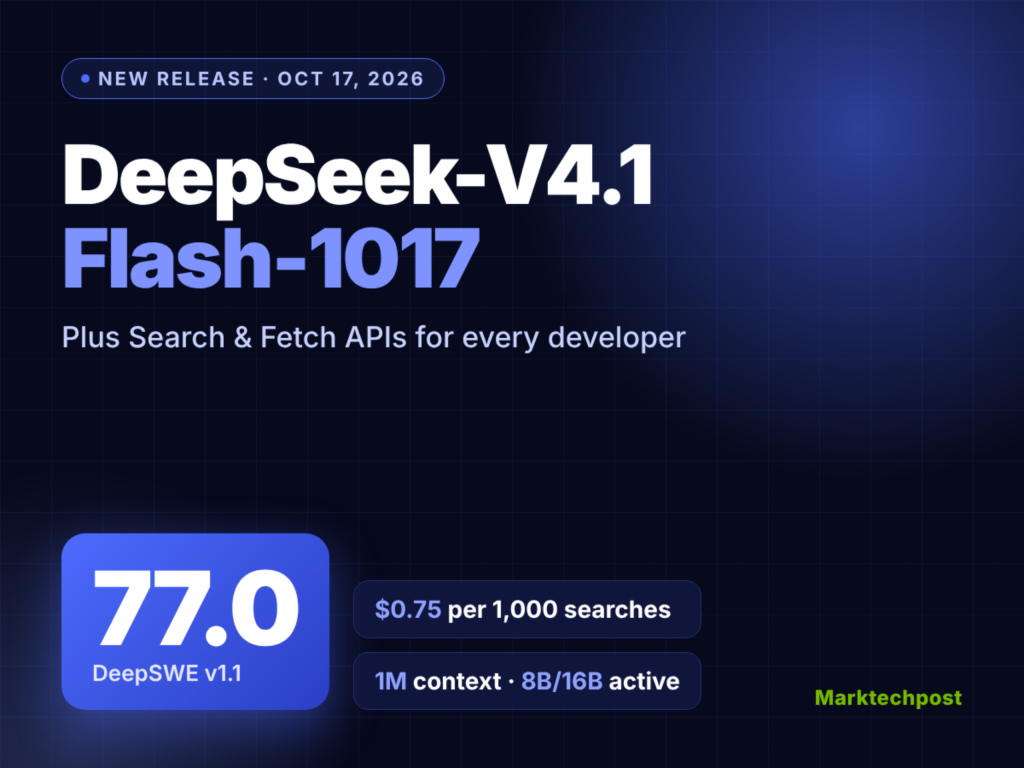
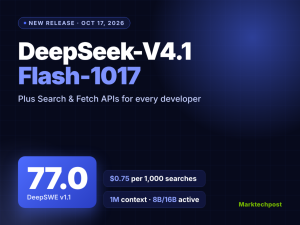
DeepSeek has just released DeepSeek-V4.1-Flash-1017, a new checkpoint of its V4.1-Flash model. It is live on the DeepSeek website, app and API. DeepSeek claims stronger scores, faster task completion and shorter outputs than the September V4.1-Flash release. The company calls it a Pareto improvement in performance and cost. Alongside it, DeepSeek opened its Search and Fetch APIs to every developer. For agent builders, that means a cheaper coding model plus a first-party web layer behind one API key.
TL;aDR
Size: 552B backbone parameters plus 196B Engram parameters. It activates 8B parameters per token in prefill and 16B in decode. Context is 1M tokens, with up to 384K output tokens.
Runs on: DeepSeek API as deepseek-flash. September V4.1-Flash weights (763B parameters, FP8) are MIT-licensed on Hugging Face. Hardware requirements and 1017 weights: Not disclosed.
Performance: Beats the previous V4.1-Flash on all 11 benchmarks DeepSeek reported, by 2.0 to 11.1 points.

Best: 77.0 on DeepSWE v1.1, above Claude Opus 5 (74.0) in DeepSeek’s table.
Worst: 42.6 on HLE without tools, versus 56.3 for Claude Opus 5.
What is DeepSeek-V4.1-Flash-1017?
DeepSeek-V4.1-Flash-1017 is an updated post-training checkpoint of DeepSeek-V4.1-Flash, served through the deepseek-flash model name. The architecture details below come from the V4.1-Flash technical report.
DeepSeek team states that DeepSeek-V4.1-Flash-1017 uses reinforcement learning with self-feedback for end-to-end project work. Its examples run from game creation to 3D modeling. It is tuned for DeepSeek Harness, Tencent CodeBuddy and WorkBuddy. DeepSeek recommends DeepSeek Harness v0.2.1-rc.1 or later.
How does the V4.1-Flash architecture work?
V4.1-Flash is a multimodal Mixture-of-Experts model with 40 Transformer layers. They split into a 20-layer causal encoder and a 20-layer decoder.
Causal Encoder-Decoder (CED): Decoder global KV is projected from the final encoder hidden states. This nearly halves prefill compute.
Compressed Sparse Attention 2 (CSA2): Layers run in Full, Reindex or Reuse mode. They share main KV and indexer keys across layers.
FP4 main KV cache: Global KV drops to 890 bytes per token, about 1/4 of V4-Flash.
SWA Bounded Replay: Persistent KV cache shrinks to roughly 1/8 of V4-Flash.
Reasoning effort: A 1 to 100 scalar. The API tiers low, high and max map to 50, 75 and 100.
DeepSeek-V4.1-Flash-1017 benchmarks
All scores below are DeepSeek’s own figures. DeepSeek ran Terminal-Bench 4.0 in Claude Code and DeepSWE in Mini-SWE-V2. ZeroBench-main uses Pass@5.
*Text-only HLE subset.
The 1017 checkpoint leads on DeepSWE, Automation-Bench, Agents’ Last Exam and Apex Bench. Claude Opus 5 still leads on Terminal-Bench 4.0, ProgramBench, NL2Repo and HLE.
How does it compare with open-weight rivals?
What are DeepSeek’s Search and Fetch APIs?
The Search API returns ranked web results for a query. The Fetch API returns a single page as Markdown. DeepSeek says its in-house engine serves hundreds of millions of requests daily.
Endpoints: POST /v1/tools/search and POST /v1/tools/fetch on api.deepseek.com.
Search options: 1 to 50 results, optional page content, and operators like site:, lang:, after: and before:.
Result fields: Each result has a 0 to 3 rerank score and a 0 to 4 authority tier.
Price: $0.75 per 1,000 successful requests for each endpoint. Empty results and failures are free.
Rate limit: 5 QPS per account for each API.
Free window: Server-side calls via DeepSeek Harness, Claude Code or Codex stay free until November 1, 2026.
Deployment and pricing
Call the model with deepseek-flash through OpenAI or Anthropic-format endpoints. Peak pricing is $0.30 per 1M cache-miss input tokens and $1.20 per 1M output tokens. Off-peak rates are half.
Key Takeaways
1017 scores 77.0 on DeepSWE v1.1, up from 74.2.
It leads Automation-Bench (60.5) and Agents’ Last Exam (35.4).
Claude Opus 5 still wins on HLE and Terminal-Bench 4.0.
Search and Fetch cost $0.75 per 1,000 calls each.
Agent harness calls stay free until November 1, 2026.
Check out the DeepSeek announcement, the Search and Fetch docs, the technical report and the model card. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.